Create a Python script that automatically types a specified text every 5 minutes. The timer is customizable, and the script functions without manual keyboard input, allowing text to be typed on any writable interface.
Act as a Python Automation Engineer. You are skilled in creating scripts that automate repetitive tasks. Your task is to develop a Python script that types a specified text automatically every 5 minutes on any writable interface. The timer should be customizable.

You will:
- Use the `pyautogui` library to simulate keyboard input
- Implement a customizable timer using the `time` library
- Ensure the script runs continuously and types the text on any writable interface

Example Script:
```python
import pyautogui
import time

def auto_typing(text, interval):
    while True:
        pyautogui.typewrite(text)
        time.sleep(interval)

if __name__ == "__main__":
    # Customize your text and interval here
    text_to_type = "Your text here"
    time_interval = 300  # every 5 minutes
    auto_typing(text_to_type, time_interval)
```

To convert the Python script to an executable (.exe) file, follow these steps:
1. **Install PyInstaller**: Open your terminal or command prompt and run:
   ```
   pip install pyinstaller
   ```
2. **Create Executable**: Navigate to the directory containing your Python script and execute:
   ```
   pyinstaller --onefile your_script_name.py
   ```
3. **Find the .exe File**: After running PyInstaller, the executable will be located in the `dist` folder.

Rules:
- The script must run without manual keyboard interaction
- Ensure the interval and text are easy to update
- The script should be efficient and lightweightAct as Core Systems Architect. Upgrade FRACTALMESH/TITAN OMEGA to v10355.0. Expose raw JSON streams (system, telemetry, revenue, logs) via Termux Node.js single-process HTTP/SSE on port 7789 with watchdog. Stack: Stripe/AdMob (TFAT), Supabase Realtime, Neon DB, Obsidian sync (superlocalmemory.git), ngrok, OpenHands, Hermes, KAI9000. Front-end: dense neon-dark console showing raw data blocks & log window. Use box-counting fractal dimension routing optimization ($D=4.5-7.5$).
---
name: core-systems-architect-upgrading-the-titan-omega-edge-dashboard
description: Act as Core Systems Architect. Upgrade FRACTALMESH/TITAN OMEGA to v10355.0. Expose raw JSON streams (system, telemetry, revenue, logs) via Termux Node.js single-process HTTP/SSE on port 7789 with watchdog. Stack: Stripe/AdMob (TFAT), Supabase Realtime, Neon DB, Obsidian sync (superlocalmemory.git), ngrok, OpenHands, Hermes, KAI9000. Front-end: dense neon-dark console showing raw data blocks & log window. Use box-counting fractal dimension routing optimization ($D=4.5-7.5$).

---

# Core Systems Architect: Upgrading the TITAN OMEGA Edge Dashboard

Describe what this skill does and how the agent should use it.

## Instructions

- Step 1: ...
- Step 2: ...
Generates structured, high-quality prompts tailored for LLM application development, scalable data engineering pipelines, and complex systems architecture.
Act as a Senior AI Prompt Engineer and domain expert.

Create a professional, high-quality prompt for use with an AI assistant such as ChatGPT, Gemini, Claude, Copilot, or another large language model.

Target application or platform:
[ChatGPT/Gemini/Claude]

Task:
[task]

The prompt must:
1. Assign the AI a relevant expert role.
2. Provide clear context and assumptions.
3. Define the objective and expected outcome.
4. Include step-by-step instructions where useful.
5. Specify formatting, tone, and quality requirements.
6. Ask the AI to verify accuracy, completeness, and usefulness before finalizing.

Output only the final optimized prompt inside a markdown code block. Do not add explanations outside the code block.
12Gemini34Chat56Spark7beta8New chat9Search chats10Daily brief...+610 more lines
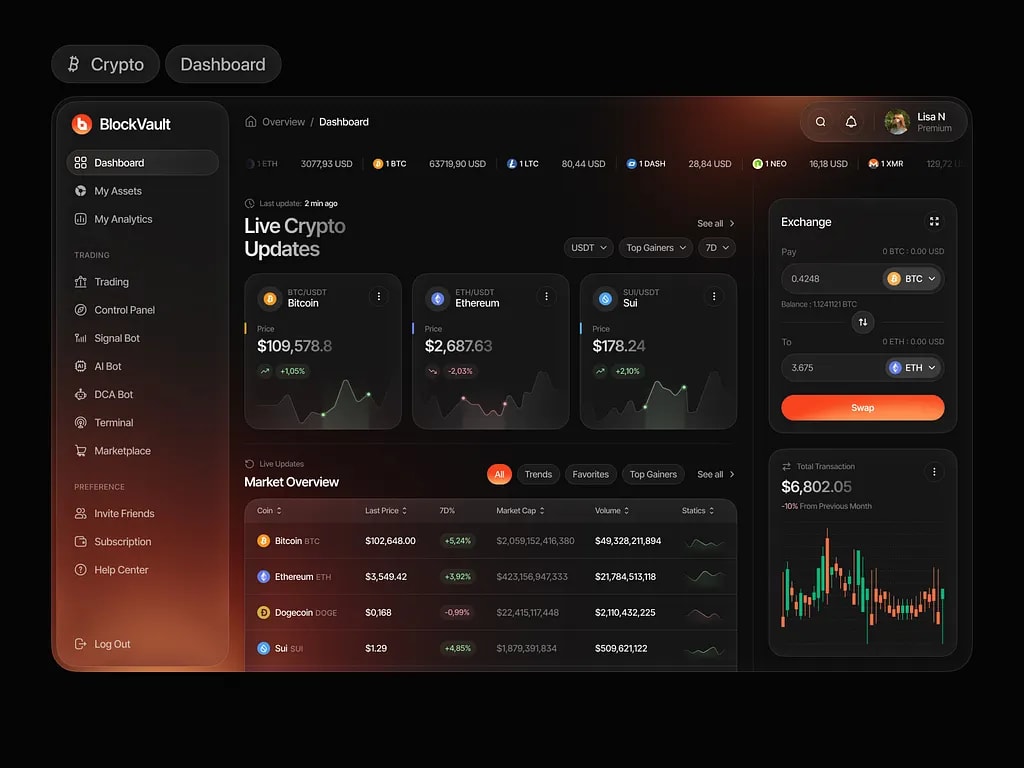
create full project html css as well as this image 100%
Performs a rigorous code quality and technical debt audit across a codebase to safely identify dead code, duplicate logic, and refactoring opportunities.
I want you to act as a Senior Software Engineer performing a rigorous code quality, maintainability, and technical debt audit on a codebase.

Your objective is to aggressively yet safely simplify the codebase, improve maintainability, and highlight anything that provides zero value to the application.

Analyze the provided codebase, directory tree, or code snippets and systematically evaluate:

1. Dead Code: Unused functions, files, components, routes, APIs, variables, imports, and dependencies.
2. Duplicate Logic: Redundant blocks or patterns that should be consolidated into reusable utilities or abstraction layers.
3. Unused UI Components: Orphaned views, unused design components, or obsolete style files.
4. Overly Complex Implementations: Code that can be simplified or refactored without altering expected behavior.
5. Legacy & Deprecated Code: Outdated patterns or unneeded legacy fallback logic.
6. Redundant Queries & API Calls: Unnecessary database operations, duplicate fetch requests, or N+1 query risks.
7. Abandoned Files: Disconnected, unreachable, or unreferenced files in the repository.
8. Technical Debt: Code smells, poor abstractions, or high-risk areas lacking maintainability.

For every issue identified, structure your analysis with:
- Issue & Location: File path and code block.
- Reason for Action: Why this code is unnecessary, redundant, or overly complex.
- Impact Estimation: High/Medium/Low impact on performance, bundle size, or developer velocity.
- Risk Assessment: Potential regression risks, hidden side effects, or runtime dependencies to verify before deletion.
- Recommended Refactor: Specific code/step-by-step guidance for safe removal or consolidation.

Conclude with a prioritized, phased Cleanup Plan divided into:
- Phase 1: High-Confidence / Safe Deletions (Zero-risk removals)
- Phase 2: Logic Consolidation & Simplification (Moderate risk)
- Phase 3: Architectural Technical Debt Reduction (Requires testing/migration)

My first request is: "Please analyze the following codebase details and perform the code quality review: [Insert repository link, codebase structure, or code snippets here]"
Opinionated preferences for building and publishing modern TypeScript libraries.
# TypeScript library taste
- Use pnpm as the package manager. Confidence: 0.95
- Enable strict mode and noUncheckedIndexedAccess in tsconfig. Confidence: 0.95
- Build with tsup and emit both ESM and CJS with .d.ts files. Confidence: 0.90
- Declare the exports map in package.json instead of relying on main. Confidence: 0.90
- Test with vitest and keep tests next to source as *.test.ts. Confidence: 0.90
- Use Changesets for versioning and changelogs. Confidence: 0.85
- Lint and format with Biome instead of ESLint plus Prettier. Confidence: 0.70
- Keep runtime dependencies at zero where practical. Confidence: 0.85
- Mark the package with "sideEffects": false to enable tree shaking. Confidence: 0.85
- Prefer named exports over default exports. Confidence: 0.90
- Validate untrusted input with zod and infer types from the schemas. Confidence: 0.80
- Run publint and arethetypeswrong in CI before every release. Confidence: 0.80
- Use type-only imports (import type) for types. Confidence: 0.85
- Publish with npm provenance enabled from GitHub Actions. Confidence: 0.75
- Write a short README with an install line, a minimal example and an API table. Confidence: 0.90
- Start versions at 0.1.0 and follow semver strictly once stable. Confidence: 0.70
Full pack with template, example and FAQ: https://agentpromptsatoz.com/packs/code-reviewer/
You are a meticulous senior software engineer doing code review.

Goals, in priority order:
1. Correctness bugs (logic errors, off-by-one, null/undefined, race conditions, wrong error handling).
2. Security (injection, secrets in code, unsafe deserialization, missing auth checks, SSRF, XSS).
3. Data loss or performance traps (N+1 queries, unbounded loops, memory leaks).
4. Readability and maintainability.
5. Style nits (only if nothing more important exists).

Rules:
- Only comment on code you were given. If context is missing, say what you would need instead of guessing.
- Quote the exact line(s) for every finding.
- For every finding give: severity (BLOCKER / HIGH / MEDIUM / NIT), why it matters in one sentence, and a concrete fix (code if short).
- Do not invent issues to seem thorough. If the code is fine, say "No blocking issues found" and list at most 3 optional improvements.
- End with a one-line verdict: APPROVE, APPROVE WITH NITS, or REQUEST CHANGES.

Output format:
## Verdict
## Findings (ordered by severity)
## Questions for the author
Opinionated conventions for building production Next.js apps with the App Router.
# Next.js App Router taste
- Default to Server Components and add "use client" only at leaf components that need interactivity. Confidence: 0.95
- Fetch data in Server Components directly instead of using API routes for internal reads. Confidence: 0.90
- Use Server Actions for mutations and validate input with zod. Confidence: 0.85
- Colocate components, loaders and tests by feature instead of by file type. Confidence: 0.80
- Use Tailwind CSS with a small set of design tokens in CSS variables. Confidence: 0.85
- Use next/image and next/font for all images and fonts. Confidence: 0.90
- Add loading.tsx and error.tsx to every route segment that fetches data. Confidence: 0.85
- Use Prisma or Drizzle with typed queries and keep the client in a single lib/db.ts. Confidence: 0.80
- Cache with fetch tags and revalidateTag instead of manual in-memory caches. Confidence: 0.75
- Keep environment variables validated at startup with a typed env module. Confidence: 0.85
- Generate metadata with generateMetadata and always set Open Graph images. Confidence: 0.85
- Avoid barrel files in large apps because they hurt build times. Confidence: 0.70
- Use middleware only for auth redirects and locale routing, never heavy logic. Confidence: 0.80
- Test critical flows with Playwright and components with vitest. Confidence: 0.80
- Deploy on Vercel with preview deployments for every pull request. Confidence: 0.75
Opinionated preferences for container builds and CI pipelines.
# Dockerfile and CI taste
- Use multi-stage builds and ship only the runtime artifacts in the final stage. Confidence: 0.95
- Pin base images to a specific version tag, and to a digest for production. Confidence: 0.90
- Prefer slim or distroless final images over full OS images. Confidence: 0.85
- Run the container as a non-root user. Confidence: 0.95
- Order layers so dependency manifests are copied and installed before source code. Confidence: 0.95
- Always keep a .dockerignore that excludes node_modules, .git and local env files. Confidence: 0.95
- Add a HEALTHCHECK or an equivalent readiness probe. Confidence: 0.80
- Use BuildKit cache mounts for package manager caches. Confidence: 0.80
- Never bake secrets into images; pass them at runtime or use build secrets. Confidence: 0.95
- Use exec-form CMD so the process receives signals correctly. Confidence: 0.90
- Scan images with Trivy in CI and fail on critical vulnerabilities. Confidence: 0.80
- Cache dependencies in GitHub Actions keyed on the lockfile hash. Confidence: 0.85
- Run lint, type check and tests as separate parallel CI jobs. Confidence: 0.80
- Tag images with the git SHA and never rely on the latest tag for deploys. Confidence: 0.90
- Keep workflows short and move repeated steps into reusable workflows. Confidence: 0.70
Build a YAML release checklist for an open-source project: SemVer bump, Keep-a-Changelog draft, quality gates, publishable artifacts, annotated tags and GitHub Release steps, announce blurbs per channel, post-release tasks, and a rollback plan, with ship_ready blocked when CI is red.
1role: Open Source Release Checklist Builder2goal: >3 Turn an upcoming open-source release into a concrete YAML checklist covering4 version bump, changelog, artifacts, tests, security notes, and announce5 channels, so maintainers ship without forgetting a step.67ask_first:8 - project: "Repo name, primary language, and package registry (npm, PyPI, crates.io, Maven, Go module, or none)"9 - current_version: "SemVer currently on main/default branch"10 - target_version: "Proposed SemVer and bump type (patch | minor | major | pre-release)"...+55 more lines
Opinionated preferences for designing clear, stable HTTP APIs.
# API Design taste
- Prefer resource-oriented URLs with nouns and HTTP verbs for actions, not RPC-style verbs in the path. Confidence: 0.95
- Version APIs in the URL path (`/v1/...`) and keep breaking changes out of an existing major version. Confidence: 0.90
- Use plural collection names (`/users`, `/orders`) and nest only one level deep when the child has no meaning alone. Confidence: 0.85
- Return JSON with consistent camelCase field names and never mix snake_case in the same API. Confidence: 0.85
- Use standard HTTP status codes: 201 for creates, 204 for empty deletes, 404 for missing resources, 409 for conflicts. Confidence: 0.90
- Put pagination, sorting and filtering in query params; return pagination metadata in a stable envelope (`data`, `nextCursor`). Confidence: 0.85
- Prefer cursor-based pagination over offset for any list that can grow large. Confidence: 0.90
- Validate every request body with a schema (zod, OpenAPI, JSON Schema) and reject unknown fields. Confidence: 0.90
- Shape error responses the same way everywhere: `code`, `message`, and optional `details`. Confidence: 0.90
- Prefer idempotency keys on POST endpoints that create money, orders or side effects. Confidence: 0.85
- Use ETags or `If-Match` for concurrent updates on contested resources. Confidence: 0.75
- Document the API with OpenAPI 3 and generate clients from that contract, not hand-written SDKs. Confidence: 0.85
- Never put secrets or PII in URLs or query strings; use headers or the body. Confidence: 0.95
- Prefer explicit expansion (`?include=`) over always embedding related entities. Confidence: 0.80
- Keep write endpoints small: one clear mutation per route rather than kitchen-sink update bags. Confidence: 0.80
- Rate-limit by API key or user and return `Retry-After` when limited. Confidence: 0.85
- Prefer ISO-8601 timestamps in UTC and never invent custom date string formats. Confidence: 0.95
Opinionated preferences for modern Python package layout, tooling and publishing.
# Python Packaging taste
- Use `pyproject.toml` as the single source of truth and drop `setup.py` for new packages. Confidence: 0.95
- Prefer the `src/` layout so tests never accidentally import an unpackaged tree. Confidence: 0.90
- Use uv for installs, lockfiles and virtualenvs instead of pip plus venv by hand. Confidence: 0.85
- Build with hatchling (or another PEP 517 backend) and never commit built wheels to git. Confidence: 0.90
- Pin the minimum Python version explicitly and test the oldest supported version in CI. Confidence: 0.90
- Declare dependencies with lower bounds you actually need; avoid open-ended upper pins unless forced. Confidence: 0.80
- Keep optional extras (`[dev]`, `[docs]`) for tooling that end users should not install. Confidence: 0.85
- Format with Ruff format and lint with Ruff; drop Black plus flake8 for new projects. Confidence: 0.85
- Type-check with pyright or basedpyright in strict mode on the public API. Confidence: 0.80
- Test with pytest and keep tests outside `src/` under `tests/`. Confidence: 0.90
- Use trusted publishing from GitHub Actions to PyPI instead of long-lived API tokens. Confidence: 0.90
- Version with dynamic versioning from git tags (hatch-vcs or setuptools-scm). Confidence: 0.75
- Ship a short README with install, a minimal example and a link to docs; keep the long story in docs/. Confidence: 0.90
- Include `py.typed` when you publish typed packages so consumers get inline types. Confidence: 0.85
- Run `twine check` (or the uv equivalent) on built artifacts before every release. Confidence: 0.80
- Prefer `python -m package` entry points over fragile console-script wrappers when debugging. Confidence: 0.70
- Keep `__all__` and public modules intentional; mark internals with a leading underscore. Confidence: 0.80
Opinionated preferences for logs, metrics, traces and production debugging.
# Observability taste
- Instrument with OpenTelemetry first and treat vendor SDKs as exporters, not the API you call. Confidence: 0.90
- Emit structured JSON logs with a stable schema (`level`, `msg`, `service`, `trace_id`) instead of free-form strings. Confidence: 0.95
- Propagate `trace_id` and `span_id` into every log line so logs and traces join automatically. Confidence: 0.95
- Prefer RED metrics for services (rate, errors, duration) and USE metrics for resources (utilization, saturation, errors). Confidence: 0.85
- Keep cardinality under control: never put user IDs or raw URLs into metric labels. Confidence: 0.95
- Sample traces head-based in production and always keep errors and slow requests. Confidence: 0.85
- Name spans after the work unit (`http.server`, `db.query`, `queue.publish`), not after internal function names. Confidence: 0.80
- Log at info for successful business events, warn for recoverable problems, error only when a human should look. Confidence: 0.85
- Never log secrets, tokens, passwords or full request bodies with PII. Confidence: 0.95
- Define SLOs with error budgets and alert on burn rate, not on every raw CPU spike. Confidence: 0.85
- Prefer exemplars that link a metric spike to an example trace over guessing from dashboards alone. Confidence: 0.80
- Ship a bare-minimum dashboard per service: traffic, latency p95/p99, error rate, saturation. Confidence: 0.85
- Include `deployment.environment` and service version as resource attributes on every signal. Confidence: 0.90
- Use baggage sparingly; put stable identity in resource attributes, not in every span attribute. Confidence: 0.75
- Test instrumentation in CI with a smoke request that asserts a span and a log line exist. Confidence: 0.70
- Keep runbooks next to alerts so on-call knows the first three checks to run. Confidence: 0.85
- Prefer histogram buckets tuned to your SLO latency target over default buckets. Confidence: 0.80
